


Table of Contents
- 1 AI SEO Optimization: How Artificial Intelligence Is Rewriting the Rules of Search
- 1.1 How modern search uses machine learning to understand intent
- 1.2 Topic planning at scale with AI assisted research
- 1.3 AI enabled content creation and optimization: workflows and controls
- 1.4 Technical SEO automation with AI driven inspection
- 1.5 Measurement and experimentation: proof over promise
- 1.6 Governance, policy and avoiding common pitfalls
- 1.7 A practical 90 day roadmap to adopt AI powered SEO
AI SEO Optimization: How Artificial Intelligence Is Rewriting the Rules of Search
AI SEO optimization is no longer an experimental add-on; it is rewriting how search interprets intent and ranks content. This article breaks down where machine learning changes the rules – from intent and topic planning to drafting, technical audits, and measurement – and where human judgment must stay in the loop. You will get a practical, tool-agnostic roadmap and specific experiments to run that measure real gains in organic performance.
How modern search uses machine learning to understand intent
Key point: Modern search systems prioritize intent and context over exact keyword matches. Google has layered multiple machine learning components – RankBrain, BERT, and MUM – to map queries to user goals, not just token overlaps (introducing RankBrain). The practical consequence is simple: content that satisfies an intent cluster wins, not the page that shoehorns a keyword into every headline.
From keywords to intent clusters
How that changes keyword selection: Stop treating keyword lists as atomic targets. Classify each query by intent – informational, navigational, transactional, and investigative – and group related queries into topic clusters that share the same user need. This is not theoretical: RankBrain and BERT improve relevance for paraphrased and conversational queries, while MUM expands signals across languages and modalities.
- Label intent: Use Google Search Console and organic query lists to tag intent at scale.
- Cluster by task: Combine similar tasks into a single content asset rather than many thin pages.
- Prioritize SERP features: Target featured snippets, People Also Ask, and product carousels when intent signals those results.
Practical limitation: Machine learning makes relevance decisions that are hard to reverse engineer. This means smaller sites risk volatility when models shift, and over-optimizing for vague intent can dilute conversion signals on product pages. The tradeoff is between topical authority and conversion clarity. Build cluster pages for discovery but keep tightly optimized transactional pages with clear signals for purchase intent.
Operationalizing intent in your workflow
Actionable step: Convert keyword research into an intent map. Pull queries from Search Console, supplement with keyword research AI and competitor SERP analysis, then assign an intent label and a priority score. Tools like Ranklytics help close the loop by turning that map into briefs and tracking ranking velocity after publication – see Top SEO AI Tools and How to Use Them in Your Workflow.
Concrete example: A SaaS project management vendor found keyword conversions plateauing despite traffic growth. They reclassified high-volume informational queries into a cluster of how-to and comparison content that fed internal links to product pages. Within eight weeks the product pages gained higher-quality referral traffic and improved conversions because the content matched searcher intent and guided users toward purchase.
Common misunderstanding: People assume more content equals better coverage. In practice, incoherent expansion – many pages loosely related to a theme – triggers thin content issues under the helpful content update. Machine learning favors cohesive assets that comprehensively serve the user task.
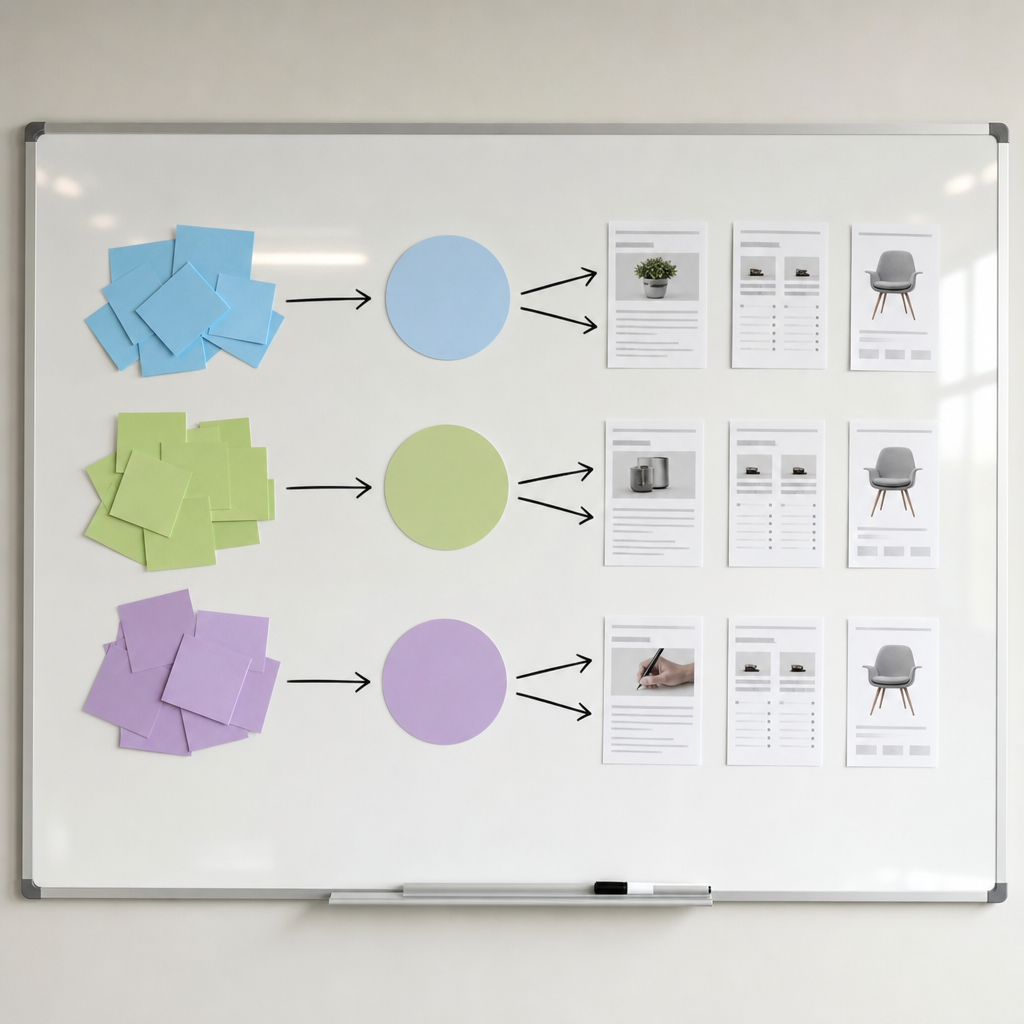
Next consideration: Start small – pick three high-value intent clusters, build cohesive assets that answer the task fully, and measure keyword velocity and conversion signals for 8 to 12 weeks before scaling the approach.
Topic planning at scale with AI assisted research
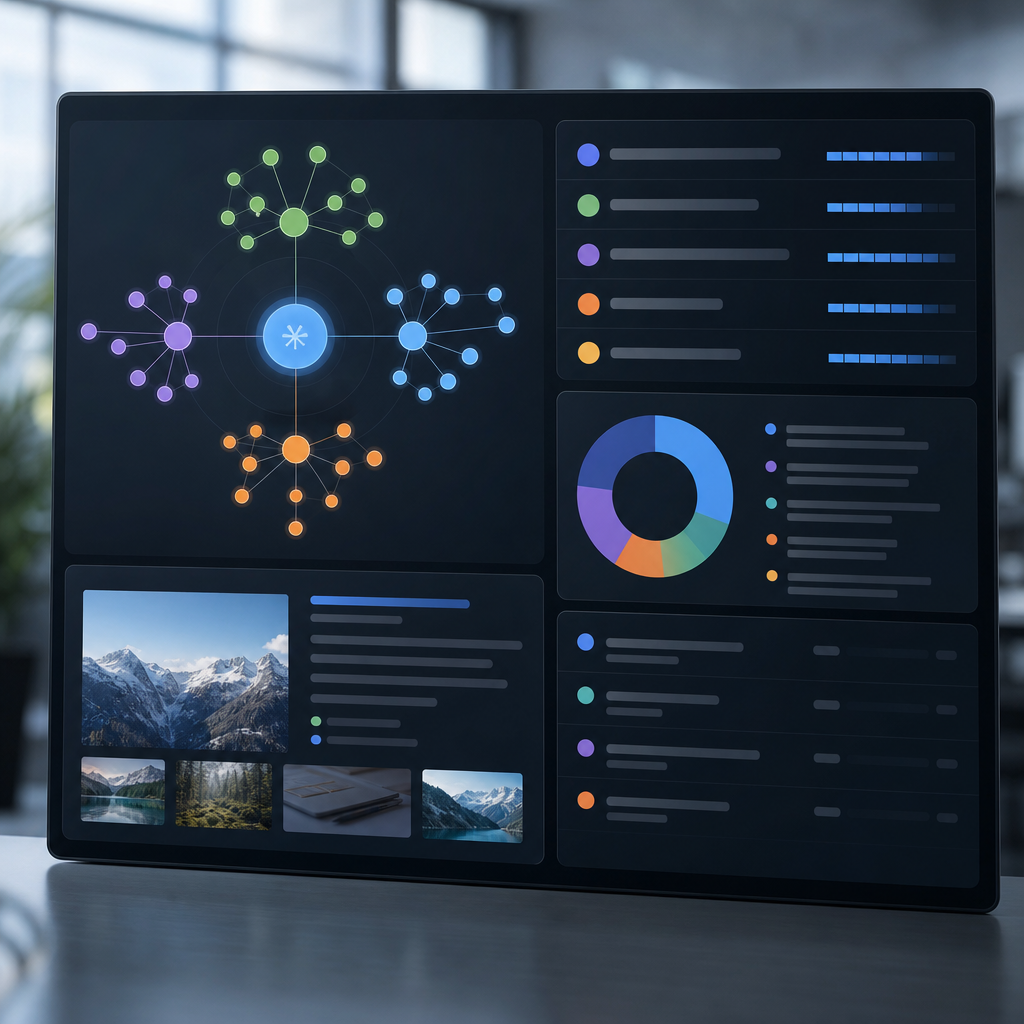
AI changes the unit you plan around from single keywords to clusters of intent. At scale, that shift matters: planning by topic clusters forces you to cover subtopics, answer related queries, and target the SERP features that actually drive clicks.
AI-assisted topic planning workflow
- Seed topics: Start with product features, high-value customer questions, and competitor pages you want to displace. Use customer support logs and paid search queries as seeds.
- SERP gap analysis: Use AI to fetch SERP feature composition and content signals for top pages, then surface missing subtopics and common questions.
- Intent labeling: Cluster queries into informational, navigational, and transactional groups using an intent classifier rather than raw keyword match.
- Priority scoring: Score clusters by traffic potential, conversion relevance, competition gap, and ease-of-win. Automate the score but cap automatic decisions.
- Brief generation: Produce structured briefs with target intent, required subtopics, SERP features to win, recommended CTAs, and a short list of sources to cite.
- Track and iterate: Push briefs into production, track keyword velocity and SERP feature capture, then re-run gap analysis every 4–8 weeks.
Practical insight: Automate the discovery and brief creation, but put humans in the loop for intent and conversion alignment. AI is fast at surfacing gaps; it is weak at subtleties like brand tone, product nuance, or regulated claims.
Trade-off to accept: Higher throughput from AI means more experiments and faster learnings, but also more editorial defects and potential for misaligned intent. Expect a 15–30 percent increase in editorial review time early in adoption as teams refine prompts, scoring thresholds, and style controls.
Concrete example: A mid-market SaaS product mapped its onboarding funnel into five seed topics. Using Ranklytics for SERP gap analysis and an intent classifier, the team generated ten cluster briefs prioritized by expected signups. Two weeks after publishing cluster pages and tracking with Ranklytics, three target queries moved into the top ten and trial signups increased for the associated landing pages.
| Signal | Why it matters |
|---|---|
| Intent match | Ensures the content answers what searchers actually want rather than chasing volume |
| SERP features present | Targets featured snippets, People Also Ask, and video when they drive clicks |
| Competitor coverage gap | Shows low-hanging topics competitors missed that are quick wins |
| Conversion relevance | Prioritizes topics that connect to revenue or qualified leads |
What people get wrong: Teams often treat AI topic suggestions as definitive roadmaps. In practice the suggestions are hypotheses. Validate with small A B tests and short measurement windows instead of committing large content budgets to unproven clusters.
Use Ranklytics Top SEO AI Tools and How to Use Them in Your Workflow for templates and tie the planning loop to ongoing tracking. Also keep Google guidance in mind: the helpful content update still penalizes content that looks like surface-level automation.
AI enabled content creation and optimization: workflows and controls
Clear premise: AI should be treated as a production partner, not a publishing shortcut. The value comes from a repeatable workflow that couples AI drafting with verification, editorial control, and measurement so you can scale without amplifying risk.
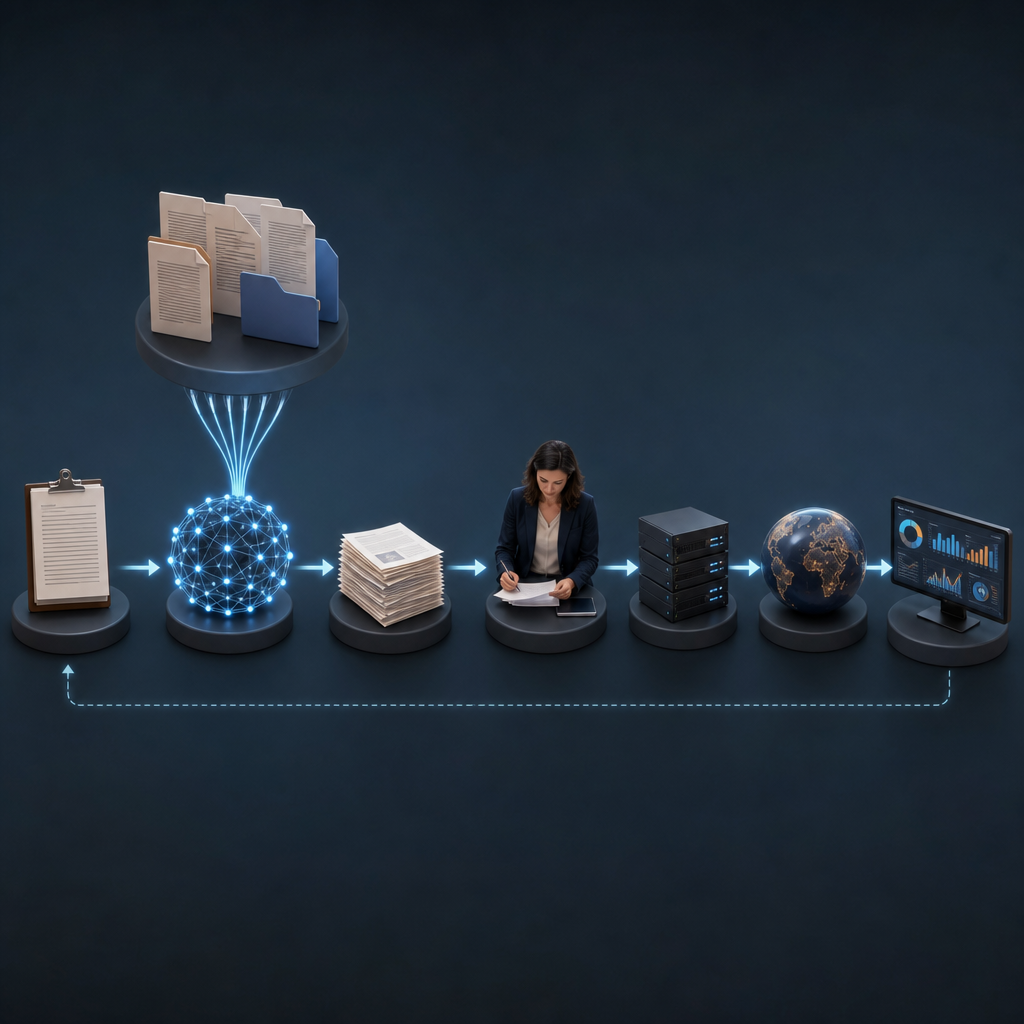
A practical workflow you can operationalize today
- Seed and brief: Create a structured brief that includes target intent, top competitor URLs, required sources, and banned claims. Use Ranklytics for keyword context and to store briefs centrally (Top SEO AI Tools and How to Use Them).
- RAG-assisted outline: Build an outline using retrieval-augmented generation so the model writes from verified documents – product docs, help center articles, and cited external sources. This reduces hallucinations compared with blind prompting.
- Draft with constraints: Produce multiple draft levels – headline/metadata, short-form summary, and full draft. Lock model temperature and include explicit instructions to cite sources and avoid speculation.
- Human verification: Assign a factual reviewer and an editorial reviewer. Use checklists for E E A T, brand tone, and legal risks. Do not publish without signoff for regulated topics.
- Pre-publish checks: Run plagiarism scans (Copyscape), accuracy spot checks, and an internal style check. Generate metadata variations for A B testing using the same brief.
- Staging and measurement: Publish to a staging or experimental folder, tag with tracking parameters, and monitor via Ranklytics keyword tracking and Google Search Console. Compare against control pages over a defined window.
Key control: Treat metadata and small copy changes as low-risk experiments you can iterate quickly. Full content replacements require longer measurement windows and stricter verification.
Quality gates, limits, and trade-offs
- Speed versus accuracy: Faster output increases the chance of hallucinated facts. Use RAG and source embedding for accuracy; accept slower throughput for authoritative topics.
- Cost versus fidelity: Higher-capacity models reduce editing time but raise costs. Reserve expensive models for drafts that need nuance or persuasion; use cheaper models for outlines and metadata.
- Automation versus human oversight: Automate repeatable tasks – outlines, metadata, internal linking suggestions – but keep humans in the loop for claims, legal language, and brand voice.
- Change velocity risk: Rapid, site-wide AI rewrites can confuse search engines and your own analytics. Stagger rollouts and document each change so you can roll back if performance drops.
Operational detail that matters: Keep a prompt library and versioned briefs. Small prompt tweaks change tone and factual accuracy; versioning gives you traceability when an experiment succeeds or fails.
Concrete example – SaaS onboarding guide
Concrete Example: A mid market SaaS creates an onboarding guide for new users. The team seeds an intent brief, uses RAG to feed product specs and support transcripts into the model, generates an outline, then drafts the article. Support engineers verify technical steps, marketing edits for tone, and the team A B tests two meta descriptions for CTR. Ranklytics tracks keyword velocity and SERP features to determine whether the guide gains organic visibility.
Why this works in practice: Feeding internal documents prevents the model from inventing steps. The split of roles – authoring by AI, verification by engineers, and narrative polishing by marketing – keeps throughput high while protecting accuracy and brand voice.
Use retrieval-augmented generation and a two-person verification loop as the minimum standard for publishable AI drafts.
For policy and search risk context, keep Google guidance in your review checklist – see Google helpful content update – and track experiments as documented changes so you can correlate publishing actions with ranking movement.
Next consideration: Decide which content classes get automated pipelines and which require SME review. Start with low regulatory risk, high traffic opportunity pages and instrument them for measurable comparison before scaling.
Technical SEO automation with AI driven inspection
Immediate point: AI reduces the time to detect structural SEO failures from days to minutes by spotting patterns in logs, crawl dumps, and SERP telemetry that humans miss when scanning spreadsheets.
What AI actually finds better than manual checks
Pattern detection: Machine learning excels at correlating multiple signals at scale. By combining server logs, crawl snapshots, and Google Search Console data an AI model can flag indexation anomalies, sudden drops in bot traffic, spikes in redirect chains, and emergent duplicate content clusters faster than rule based scripts.
- Crawl anomalies: unusual bot activity, sudden drop in pages crawled, or crawl budget saturation caused by parameter proliferation
- Redirect and chain analysis: long chains and loops that inflate latency and waste crawl budget
- Indexation gaps: pages crawled but not indexed with clustered reasons instead of single line items
- Page regressions: mobile rendering failures, Core Web Vitals regressions correlated with recent deployments
- SERP feature losses: sudden disappearance from featured snippets or product rich results tied to structured data changes
Practical limitation: AI is good at surfacing hypotheses not at deciding corrective action in every case. Automated detection yields many false positives unless you tune thresholds and feed the model quality labels from your engineering and SEO teams.
Operational workflow to make AI inspection actionable
- Ingest sources: server logs, crawl exports, Google Search Console, sitemap snapshots, and uptime monitoring
- Baseline and anomaly detection: run a rolling 30 day baseline, surface deviations with confidence scores
- Triage playbook: map confidence score to action: Monitor only, Create ticket, or Hotfixes requiring rollback plan
- Automated evidence: attach crawl snippets, log excerpts, and example URLs to tickets so engineers see the failure pattern
- SLA and measurement: weekly health score, time to remediation, and postfix validation checks
Concrete example: An ecommerce site experienced a 40 percent drop in bot hits overnight. AI inspection correlated the drop with a surge in 3xx chains and parameterized URLs created by a recent search session tracking change. The system created high priority tickets for removing the parameterized sitemap entries and deploying canonical headers and the team tracked recovery in crawl rate and indexation over the next 10 days.
Judgment you need to accept: Automating detection without an ownership model creates noise overload. Teams that win assign a single owner per alert class, enforce a human signoff on structural fixes, and keep rollback plans ready for changes that affect canonicalization or global redirects.
Core rule: use AI to prioritize and provide evidence, not to push sweeping fixes without human review. Automated remediation needs tight guardrails.
Data and privacy considerations: Log ingestion can include PII in query strings. Mask sensitive tokens, keep retention short, and verify compliance with legal and privacy teams before centralizing logs for model training.
Where to start: run a 4 week pilot that compares manual audits against AI driven alerts, measure false positive rate, time saved, and remediation success. Use that pilot to set thresholds and SLAs before widening automation to production.
Next consideration: after you stabilize detection, add predictive analytics to estimate which technical fixes will most likely recover organic traffic so engineering time is spent where it moves rankings. For a practical guide to tool driven audits see Moz on AI and SEO.
Measurement and experimentation: proof over promise
Key point: AI driven changes are hypotheses, not magic. Treat every AI intervention as an experiment you must measure end to end – from query to conversion – or you will confuse activity for impact.
What to measure and how long to wait
Metrics that matter: Track organic sessions, keyword velocity for targeted terms, click through rate for SERP listings, share of SERP features, and downstream conversions. Use ranking shifts alone as signals, not proof; ranking moves without traffic or conversion lift are often noise or SERP volatility.
- A B test – metadata: Run controlled title and meta description variants on matched page cohorts. Measure CTR and sessions over 4 to 6 weeks and watch for CTR to translate to visits before assuming impact.
- Refresh vs new page: Pick a topic cluster and split similar queries between refreshed pages and new pages. Track keyword velocity and ranking diversity for 8 to 12 weeks to avoid misreading short term ranking swings.
- Pillar cluster test: Publish a pillar plus cluster batch and compare organic growth against a matched control topic that did not receive new content. Expect measurable changes in keyword breadth after 10 to 12 weeks.
Tradeoffs and limitations: Faster experiments – like metadata A B tests – give quick signals but smaller downstream conversion impact. Larger content experiments take longer and require matching controls to isolate effect. Do not run multiple large experiments at once on the same URL set or you will not be able to attribute outcomes.
Statistical rigor matters: Use control groups or staggered rollouts, and predefine success thresholds. Small sample sizes and seasonality produce false positives. If a test yields an early ranking gain, keep the control live until the measurement window closes before rolling out changes broadly.
Concrete example: A SaaS marketing team used Ranklytics to run a metadata A B test on 40 landing pages and a content refresh on 12 resource pages. The metadata variant produced an 18 percent CTR lift and a 12 percent rise in organic sessions within 5 weeks; conversion lift appeared only after the 10 week mark when internal funnel changes were synchronized. The team kept the control group until week 12 to confirm durability before scaling the new templates site wide.
Proof over promise: a measured, repeatable experiment that links AI changes to traffic and conversions beats anecdote and dashboard vanity metrics every time.
Practical judgment: Most teams overestimate how quickly AI changes will show ROI and underestimate confounders like algorithm updates or seasonal traffic. Automate monitoring for anomalies, use Google helpful content update guidance when evaluating quality, and link experiments to a measurable business outcome before you call an initiative successful.
Governance, policy and avoiding common pitfalls
Governance is not optional. AI accelerates volume but also multiplies mistakes, and those mistakes show up in search rankings, brand risk, and legal exposure faster than manual processes did.
Practical control framework. Treat AI content like a software release: require provenance tagging, versioned model details, role based approvals, and a visible audit trail that links each published page back to the draft, prompts used, and reviewer signoffs. The tradeoff is simple – tighter gates slow throughput but prevent large visibility regressions that cost weeks to recover.
Policy risks that actually change behaviour
Search policy matters in practice. Google has made clear guidance with the helpful content update and earlier machine learning systems like RankBrain show the search ecosystem rewards helpful, experience led content. Mass produced, thin, or misleading content still ranks poorly and can suppress whole topic clusters for a site.
Concrete example: A SaaS support team used AI to auto draft FAQ pages and published 120 pages in two weeks. Within a month organic traffic to the support section dropped because drafts reused stock phrasing and failed to answer user intent. The recovery required manual rewrites and a rollback of low performing pages. If the team had enforced a simple threshold – require at least two authoritative citations or SME signoff for any page covering product limitations – this would not have happened.
Legal and brand safety considerations. If content makes claims about health, finance, or regulated outcomes, do not rely on general purpose public models without expert review. Protect customer data by redacting PII before sending prompts to third party APIs, and include model usage clauses in vendor contracts to limit training data reuse. The tradeoff is cost: private models and additional review increase spend, but remove material legal and reputational risk.
Model drift and monitoring. AI models change, your prompts will change, and ranking signals evolve. Instrument continuous checks that compare pre and post publish performance for a defined window – for example CTR, time on page, and keyword velocity at 14 and 60 days. Set automatic rollback or alert rules for >30 percent negative deltas on key metrics. Overly aggressive alerting creates noise; calibrate thresholds against domain authority and historical variance.
- Governance checklist: Add provenance metadata to each page including model name, prompt hash, and reviewer id
- Publish thresholds: Define automated pass criteria such as minimum source citations, plagiarism score, and AI confidence or similarity metrics
- Human in loop rules: Require SME signoff for legal, medical, or claims driven content and for any content older than 12 months that is auto refreshed
- Vendor controls: Prohibit sending PII to public APIs and require contractual limits on training data reuse
- Monitoring: Schedule 14 and 60 day performance checks with automatic alerts for negative CTR or ranking velocity
Where to start next. Map your content types into risk tiers – low, medium, high – then apply the checklist above. Use tools and playbooks like the Ranklytics Top SEO AI Tools and How to Use Them in Your Workflow to pick models that support versioning and logging, and consult the Ranklytics The Pros and Cons of AI in Content Writing for operational tradeoffs.
A practical 90 day roadmap to adopt AI powered SEO
Start with outcomes, not tools. Commit to three measurable outcomes for the 90 day window (example: +15% organic sessions for target cluster, +20% CTR for top 10 keywords, two new SERP features captured). This prevents endless tool-shopping and forces clear success criteria for any AI SEO optimization work.
Month 1 — Audit, pilot experiments, and establish baselines
- Week 1: Baseline audit. Produce a focused inventory: 50 priority pages, current keyword rankings, page-level CTR, average time on page, and technical health scores. Use Ranklytics SEO Inspection for the audit and export data for experiments.
- Week 2: Select pilots. Pick 3 test candidates that are high impact but low risk: one metadata-only test, one content refresh, one new topic page. Each must have minimal recent algorithm changes and at least some historical impressions to measure velocity.
- Week 3: Draft playbooks. Create a one‑page quality gate for AI drafts: factual sources, E E A T checklist, plagiarism threshold, editorial signoff, and publish cadence.
- Week 4: Run quick pilots. Publish metadata A/B tests (titles and meta descriptions), and an AI-assisted content refresh behind the quality gate. Capture pre/post baselines and schedule a 6–10 week observation window.
Month 2 — Scale production under strict quality control
- Week 5–6: Expand to 12 pages. Use the same process: topic brief, AI draft, editor verification, evidence links, publish. Limit automation to drafting and metadata generation — keep humans in the loop.
- Week 7: Run controlled experiments. Launch two measurable experiments: A/B headline/meta test across matched pages; cluster vs single-page test (create a pillar and two cluster pages). Define statistical windows and minimum sample size before drawing conclusions.
- Week 8: Triage and learn. Use keyword velocity, CTR, and early ranking changes to prune approaches. Stop formats that show negative movement after 6 weeks. Document what failed and why.
Month 3 — Automate monitoring, codify playbooks, and decide scale
- Week 9: Instrument continuous tracking. Automate keyword tracking and anomaly alerts for the experiment cohorts using Ranklytics and GSC exports. Set thresholds for rollback (e.g., -10% impressions or -8% CTR over 14 days).
- Week 10: Build the playbook. Convert successful experiments into repeatable templates: briefs, prompt library, editorial checklist, and publishing cadence.
- Week 11–12: ROI and scaling decision. Compare lift vs cost (content production hours, editing time, any paid credits). Choose one of three outcomes: scale to 50 pages/month, iterate a second experiment cycle, or narrow scope to metadata-only optimization.
Practical limitation and trade-off. Faster output increases risk of drifting away from user intent and brand voice. In practice, teams that prioritize throughput without tightening editorial controls see higher short-term volume but negligible long-term ranking gains. Prioritize signal (measured lift) over volume.
Concrete Example: A mid-market SaaS with existing domain authority ran this roadmap. Month 1 they A/B tested title tags on 10 product pages and saw a 12% CTR lift in four weeks. Month 2 they published six AI-assisted help articles under strict sourcing rules; two pages gained top 10 placements in eight weeks. Month 3 they automated alerts and moved to a production cadence of three validated articles per week.
Decision rule: If validated experiments produce a reproducible lift and cost per lift is acceptable, scale. If results are noisy or negative after the observation window, stop and rework prompts, briefs, or editorial rules.
Plan for one additional constraint: statistical power. Small sample pilots are fast but often inconclusive. If you need definitive answers for high-value pages, accept longer observation windows or larger cohorts.
If you want a ready checklist for the audit and pilot templates, see Top SEO AI Tools and How to Use Them in Your Workflow and reference the Google helpful content guidance when designing editorial signoffs.

Written by
ranklytics