

Table of Contents
- 1 Crawl Budget, Pogo Sticking, and Indexation: The Technical SEO Concepts Killing Your Rankings
- 1.1 How Crawl Budget Works and Why It Matters for Medium and Large Sites
- 1.2 Measuring Crawl Waste: Tools, Metrics, and a Quick Audit Checklist
- 1.3 Common Crawl Budget Drainers and Exact Fixes
- 1.4 Diagnosing and Reducing Pogo Sticking That Triggers Ranking Drops
- 1.5 Indexation Failures That Hide Your Best Pages
- 1.6 Priority Remediation Playbook and Sprint-Friendly Tasks
- 1.7 Case Examples, Playbook Templates, and Tracking With Ranklytics
Crawl Budget, Pogo Sticking, and Indexation: The Technical SEO Concepts Killing Your Rankings
When rankings fall without a clear content issue, three technical problems are usually the real cause: technical seo crawl budget waste, pogo sticking that signals intent mismatch, and indexation errors that hide your best pages. This how-to guide shows how to prove which of the three is hurting your site using server logs, Google Search Console signals, targeted crawls, and Ranklytics, then delivers a prioritized, sprint-friendly remediation plan you can assign or implement from the CMS. Expect concrete diagnostics, exact fixes for common failure modes, and a monitoring checklist so you can measure recovery in days to weeks rather than guessing.
How Crawl Budget Works and Why It Matters for Medium and Large Sites
Crawl budget is practical, not theoretical: it determines how often Googlebot visits your site and how quickly new or updated, high-value pages get discovered. For medium and large sites with hundreds of thousands of indexable URLs, poor crawl efficiency translates into the real cost of delayed indexing and missed ranking windows.
How search engines treat crawl budget in practice
Think of crawl budget as two interacting forces: crawl rate limit (server tolerance and politeness) and crawl demand (pages Google wants to fetch). A healthy site with fast server response times and clear architecture increases the rate limit; removing low-value, noisy URLs reduces demand. Both sides matter for crawl efficiency.
- Top culprits that waste crawl budget: parameterized and faceted URLs, redirect chains, soft 404s, auto-generated session or calendar URLs, and near-duplicate tag/category pages
- Diagnostics that reveal a constraint: low pages crawled per day in Google Search Console relative to total indexable pages, long time between publish and index, and server log evidence of Googlebot hitting low-value paths repeatedly
- Common misunderstandings: blocking via
robots.txtprevents crawling but also prevents resource fetching needed for rendering; noindex removes pages from the index but does not stop Google from crawling them if they are discoverable
Practical trade-off: blocking large swaths of URLs with robots.txt reduces crawl load quickly but can break indexing for resources that need rendering or for pages that should be consolidated. A safer, often better route is a mix of canonicalization, selective noindex, and sitemap hygiene so you guide Google to the pages you want crawled and indexed.
Concrete Example: An ecommerce site had 2 million parameter URLs from faceted navigation. New product pages took two to three weeks to appear in search results. After applying canonical rules, removing low-value facets from sitemaps, and adding parameter handling, discovery time for priority SKUs dropped from weeks to two to three days and organic conversions recovered on high-margin SKUs.
How to check fast: use Google Search Console crawl stats and Coverage to spot patterns, pair that with a 48 to 72 hour server log sample to map where Googlebot actually spends time, and run a focused crawl with Screaming Frog or Sitebulb to surface redirect chains and duplicate content. Surface-level internal linking fixes rarely help when the root cause is explosive URL generation.
Next step: run a 48 hour server log extraction and map the top 1,000 Googlebot hits to URL types. That single dataset tells you whether to fix server response time, collapse redirects, or stop low-value URL generation first.
Measuring Crawl Waste: Tools, Metrics, and a Quick Audit Checklist
Start with three sources you can trust. Use server logs for truth about Googlebot behavior, Google Search Console for trends and coverage, and an active crawler like Screaming Frog to reproduce URL-level problems. Together these show where crawl time is spent and which pages are low-value drains.
Key metrics to capture first
- Googlebot hit distribution: percent of bot hits by path segment or parameterized pattern (identify hotspots consuming >20 to 30 percent of crawl).
- Crawl to index ratio: number of unique URLs crawled per day versus number actually indexed; a low conversion suggests wasted crawl or indexing blockers.
- Time to first index for new high-value pages: if high-priority pages take longer than a week to appear, treat that as a red flag.
- Server response mix: percent 200 versus 3xx/4xx/5xx on Googlebot requests; redirect chains and soft 404s are crawl sinks.
- Internal link depth and crawl depth analysis: average clicks from homepage to top pages; deep, thin pages are crawled less often.
- Sitemap vs indexed pages mismatch: count of sitemap URLs not indexed and indexed pages not in sitemap.
Practical limitation: Benchmarks are relative. There is no universal pages-crawled-per-day threshold that proves constraint. Your judgment must combine these metrics with traffic value. A high-volume blog with low-value tags is fine to ignore; a product landing page that never gets crawled is not.
Quick audit checklist – prioritized and actionable
- Export GSC coverage and crawl stats for 90 days. Look for spikes in server errors and for consistently low pages crawled per day relative to site size. See Google Developers for crawl budget context.
- Pull 30 days of server logs and map Googlebot hits to URL patterns. Calculate percentage of hits going to parameterized, calendar, session, or print URLs.
- Run an active crawl with rendering enabled. Use Screaming Frog to find redirect chains, canonical mismatches, and indexable duplicates. Reference Screaming Frog guidance at Screaming Frog.
- Cross-reference sitemap, GSC index coverage, and organic landing pages. Flag sitemap omissions for pages that drive impressions or conversions.
- Score pages by traffic potential versus crawl cost. Prioritize fixes where high potential and high crawl cost intersect; low-value pages with low traffic potential can be noindexed or removed.
- Spot-check new content indexing lag. For 10 recent high-priority pages, record publish time and first index time to benchmark recrawl speed.
- Verify robots and canonical policy. Ensure noindex, canonical, or robots blockage isn't accidentally hiding high-value pages.
- Create a 14-day measurement plan. After fixes, track pages crawled per day, time to index, and organic impressions for remediated pages.
Trade-off to accept: Deep structural changes like reworking faceted navigation or URL rules take engineering time. If bandwidth is limited, implement targeted noindex and sitemap fixes first. Those moves reclaim the most immediate crawl capacity with the least dev effort.
Concrete example: A mid-market SaaS knowledge base logged 60 percent of Googlebot requests on calendar pagination and print view URLs that produced almost no organic traffic. After applying targeted noindex rules and consolidating canonical tags, time to index for core docs dropped from about 12 days to 3 days and impressions for priority queries began recovering within four weeks.
Judgment you need to make: Stop treating crawl metrics as vanity. If a behavior uses significant bot time and yields negligible organic value, act fast. Teams obsessing over minor page speed gains or structured data before reclaiming crawl capacity are often wasting limited engineering cycles.
Next step: run the checklist on one site section this week, prioritize the top three fixes by traffic impact and implementation effort, then measure crawl and index changes over 14 days.
Common Crawl Budget Drainers and Exact Fixes
Key point: If Googlebot spends its time on low-value URLs, your important pages will be discovered and reindexed more slowly. The fixes below are specific – not theoretical – and you can prioritize by traffic impact and implementation effort.
Faceted navigation and parameterized URLs
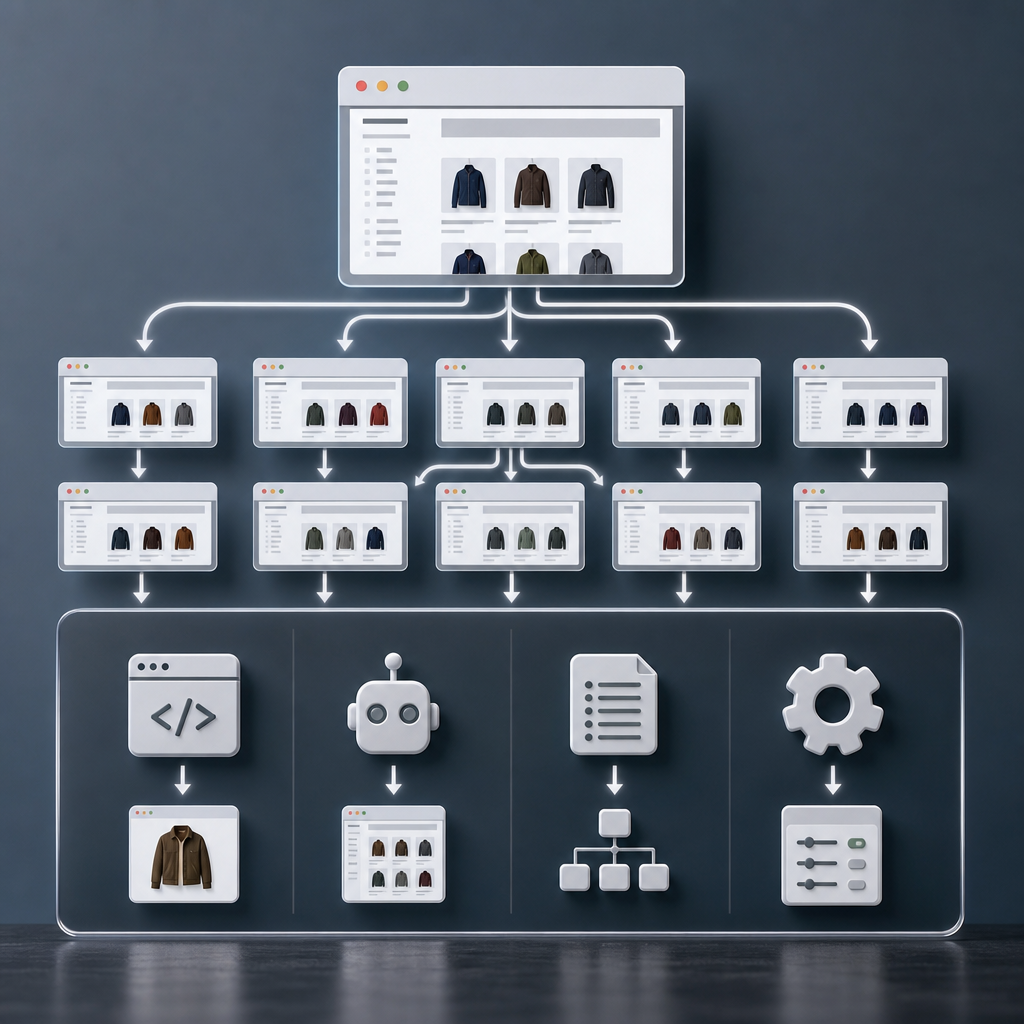
Problem: Facets and query parameters generate combinatorial URL explosions and are the single most common crawl budget drainer on ecommerce and large content sites.
- Exact fix – canonicalization: Canonical every parameterized view to the closest representative page when the content does not materially change. Avoid canonical chains.
- Exact fix – parameter handling in Search Console: Use Google Developers guidance to declare parameters when they only sort or filter display, not change primary content.
- Exact fix – selective noindex: Add meta noindex to deep or combined-filter pages that deliver negligible organic value, but only after confirming they have no inbound links or traffic.
Tradeoff: Overzealous noindex or parameter blocking will hide legitimately useful variant pages. Always cross-check traffic and internal link equity first.
Uncontrolled URL generation and session IDs
Exact fixes: Stop appending session or analytics IDs to crawlable URLs, implement canonical rules that strip those parameters, and configure your CMS to avoid creating duplicate print or share URLs as separate indexable pages.
Practical consideration: Some legacy systems require dev time to change URL generation. Short-term, use robots meta noindex or X-Robots-Tag on parameterized responses while engineering schedules the proper fix.
Redirect chains, soft 404s, and server errors
Exact fixes: Collapse redirect chains so each landing page returns a single 301 to the final URL, convert soft 404s into proper 404 or 410 where content is intentionally removed, and fix 5xx errors quickly – these responses consume Googlebot time without value.
- Fix redirect chains: Prioritize top landing pages and collapse multi-hop redirects to a single hop.
- Return proper status codes: Use 410 for permanently removed content when you want faster deindexing.
- Stabilize server response time: Implement caching and rate-limiting safeguards against spikes that trigger crawl slowdowns.
Judgment: Fixing redirects on the handful of top organic landing pages almost always gives better short-term ROI than sweeping sitewide refactor work.
Large low-value archives, duplicate content, and internal linking
Exact fixes: Remove low-value tag and archive pages from the sitemap, consolidate similar content into canonical pages, and strengthen internal links to priority pages so Googlebot follows meaningful paths instead of crawling shallow tag lists.
Real-world example: An ecommerce site had millions of parameter URLs from color and size filters. The team implemented parameter handling in Search Console, added meta noindex for combined-filter pages, and removed non-converting tag pages from the sitemap. Within three weeks product pages were crawled more frequently and several previously stalled product pages regained organic impressions.
Do not use robots.txt to block CSS or JS needed for rendering. Blocking resources can cause Google to view a page as broken and increase crawl inefficiency.
Where to look next: Use server logs to confirm Googlebot hit patterns, run a focused crawl with Screaming Frog to map redirect chains and parameter duplicates, and surface the highest-impact issues in your next sprint using the SEO Inspection guide.
Diagnosing and Reducing Pogo Sticking That Triggers Ranking Drops
Pogo sticking is usually a content-intent failure, not a mystery algorithm change. Users click your result, decide it does not answer the query, and return to the SERP quickly — that repeated signal tells search engines the page is a poor match. Fixes are a mix of snippet-level controls, immediate on-page improvements, and measured experiments; treat this like conversion optimization for organic traffic, not a link-building problem.
How to detect pogo sticking in the wild
Practical detection relies on stitched signals because no single report gives you return-to-SERP events. Build a reproducible diagnostic using three data sources: analytics session sequencing, Search Console query-level trends, and on-page behaviour (heatmaps or event timers). Use Moz and Ahrefs to understand signal logic, then apply it to your data.
- Create an organic-entry short-dwell segment: Filter sessions with referrer containing google, time on page under 8–12 seconds, and no downstream pageviews. Track that segment over affected queries.
- Cross-reference with Search Console: Look for queries where clicks remain high or CTR spikes while impressions or positions drop — a classic sign users click then bounce and Google demotes the result.
- Add behavior telemetry: Use a simple on-page timer event (first interaction or time-to-scroll) or heatmaps to confirm most users leave before interacting.
Limitation to accept up front: you will never measure return-to-SERP perfectly without instrumenting session stitching across touchpoints and search results. Work with proxies. Short dwell plus immediate re-entry to search is good enough to prioritize fixes; obsessing over perfect measurement wastes time.
Prioritized remediation steps that actually move rankings
- Fix the SERP promise first: Align title and meta description to the page content; stop using clickbait titles. If the snippet over-promises, users will pogo stick even if the page is excellent.
- Answer the query above the fold: Put the primary answer or next action where the user sees it immediately — a clear H1, a short summary, or a featured code block for how-to queries.
- Reduce friction and visual blockers: Remove intrusive interstitials, compress large hero images, and address slow TTFB. Page speed matters more for pogo sticking than for crawl budget optimization.
- Add intent-signalling structured data: Use appropriate schema to help create an accurate snippet; it reduces mismatch-driven clicks without engineering heavy changes.
- Run a narrow A/B test: Test meta+content changes on a set of mid-tail queries and measure organic dwell and rank movement using Ranklytics or your keyword tracker before rolling sitewide.
Trade-off to consider: lowering CTR intentionally by making snippets less sensational can reduce immediate clicks but improve long-term rankings if it stops pogo-sticking. You must prioritize high-intent pages where rank stability matters over chase-for-clicks pages that generate low-quality traffic.
Concrete Example: A SaaS documentation page ranked for a mid-tail how-to query but suffered a sudden position drop. Diagnostics showed organic entries with median dwell under 9 seconds and heatmaps where users scrolled past the answer. The team rewrote the intro to show the solution in the first 250 pixels, simplified the meta to match query intent, and cut page load time by fixing a blocking script. Within three weeks the short-dwell segment fell 45% for that query and rankings recovered to previous positions.
If you see high clicks + short dwell on a high-value query, prioritize snippet alignment and above-the-fold answers before chasing backlinks or large structural changes.
Final judgment: Pogo sticking is fixable and often low-cost compared with large architecture work, but it requires deliberate measurement and willingness to change what attracts clicks. Treat intent alignment and first-impression content as product decisions; engineering helps with speed and interstitials, but the fastest wins are usually content and snippet fixes.
Indexation Failures That Hide Your Best Pages
Indexation failure is usually a human configuration mistake, not a mysterious algorithmic demotion. High-value pages frequently disappear from results because they were accidentally blocked, canonicalized away, or omitted from sitemaps — and those problems are easy to miss in routine audits.
What actually hides pages (and why it matters)
Accidental blockers outrank content quality. A page with perfect intent-match and backlinks still gets zero impressions if it carries a noindex, is pointed to by a wrong canonical, or is unreachable to Googlebot because of robots.txt. The practical consequence: teams chase content rewrites while the underlying page is simply unindexable.
- Noindex slips: CMS templates, staging pushes, or migration scripts add
noindexacross sections and nobody notices until traffic drops. - Canonical mistakes: Canonicals should consolidate duplicates, not send your best landing pages to a generic overview page.
- robots.txt and blocked resources: Blocking CSS/JS or entire folders prevents rendering and can stop Google from understanding page structure.
- Sitemap mismatches: Inclusion in a sitemap does not guarantee indexing; omission slows discovery for low-linked pages.
Trade-off to accept: marking many low-value pages as noindex reduces crawl load but also cuts long-tail discovery. Choose selective noindexing driven by traffic and keyword potential, not blanket rules that feel safe.
A practical, scale-friendly audit
Cross-reference three sources before declaring a page healthy. Use your XML sitemap, Google Search Console Coverage, and a sampled site: operator check to confirm a page is both discoverable and indexed. Supplement with server logs to confirm Googlebot actually requested the URL.
- Quick check: Search Console Coverage for excluded reasons and compare against your sitemap entries.
- Server evidence: Identify whether Googlebot received 200, 301, 404, or blocked responses from logs.
- Priority recovery: For revenue or high-traffic pages, remove accidental
noindex, correct canonical tags, unblock in robots.txt, then resubmit the sitemap and use URL Inspection sparingly for confirmation.
Limitations to keep in mind. The URL Inspection tool is useful for one-off checks but not for bulk validation; resubmitting many URLs to force reindexing can backfire if the underlying issue persists. Also, a sitemap resubmission does not guarantee immediate recrawl — internal linking and server response time matter as much as the sitemap.
Concrete Example: A SaaS documentation site lost organic entries for several how-to guides after a migration where canonical tags on subpages were set to the main docs hub. Fixing the canonicals and resubmitting the sitemap recovered indexed status for the pages within 10 days; traffic and keyword ranks followed when Ranklytics tracked the index state changes and correlated them with impressions.
Fastest wins come from removing accidental noindex and fixing incorrect canonicals on pages with existing impressions — these actions often restore visibility faster than content rewrites.
Next consideration: before investing in large-scale content work, verify indexability. Fixing indexation errors is cheap, fast, and often the only thing standing between your best pages and measurable organic traffic recovery. For a repeatable approach, see the Ranklytics audit workflow in this guide: SEO Inspection: A Step-by-Step Guide to Optimizing Your Site's Health.
Priority Remediation Playbook and Sprint-Friendly Tasks
Start here: pick three measurable goals you can complete in a sprint and insist on acceptance criteria. Technical SEO fixes fail in practice when they are vague or when engineering does the change without anyone validating the outcome. Define what success looks like before asking for work.
Sprint structure and examples
- Sprint 0 – Triage and baseline: capture pre-change KPIs for target pages – crawls per day, time-to-index, impressions for top queries, and server response sampling. Use server logs and Ranklytics alerts to create evidence for prioritization.
- Sprint 1 – Quick wins (1 week): fix high-traffic soft 404s, collapse redirect chains on top landing pages, remove accidental noindex on revenue pages. These are low effort and produce observable indexation and impressions changes quickly.
- Sprint 2 – Medium work (2 to 4 weeks): implement canonical policies for parameterized URLs, prune low-value tag pages from sitemaps, and add focused internal links to orphaned money pages.
- Sprint 3 – Platform changes (4 to 8 weeks): introduce parameter handling rules in CMS, add server-side redirects to eliminate chains, and implement rate-friendly caching or edge rules to lower server response time for Googlebot.
| Task | Traffic potential | Crawl cost | Dev effort | Expected impact | Priority |
|---|---|---|---|---|---|
| Remove accidental noindex on top landing pages | High | Low | Low | Immediate return to indexability and traffic | High |
| Collapse redirect chains for top 50 landing pages | High | Medium | Medium | Faster crawl depth and less wasted bot time | High |
| Noindex parameterized faceted URLs | Medium | High | Low | Frees crawl capacity for canonical pages | Medium |
| Architectural faceted navigation rewrite | High | Very high | High | Long term crawl efficiency improvements | Low – backlog |
Practical tradeoff: using noindex on parameter pages is fast and effective but blunt. It reduces crawl waste quickly yet can remove internal link value those pages pass to canonical pages. Prefer noindex as a stopgap while you design canonicalization or URL structure changes.
Engineer request template and acceptance criteria
- Action: concise description of change and exact pages affected
- Why: traffic and crawl evidence with Ranklytics or Search Console links
- Success metrics: e.g., pages crawled per day +20 percent for path, time-to-index under X days for new publishes, impressions for target keywords +Y percent
- Validation steps: verify server logs show reduced Googlebot hits on excluded URLs, confirm Search Console Index Coverage moves from excluded to valid, track keyword position in Ranklytics for 14 days
- Rollback plan: how to revert the change and who owns verification
Concrete example: an ecommerce site had millions of faceted parameter URLs that consumed 60 percent of Googlebot hits. The team ran a one-week sprint to add selective noindex to low-value parameter combinations, update the XML sitemap to focus on canonical product pages, and add internal links to the canonical variants. Within two weeks crawled pages per day shifted back to product pages and impressions for target SKUs began recovering.
Do not ask for broad site changes without a measurable pilot. Small pilots prove ROI and unlock engineering priority.
Next consideration: after each sprint, compare pre and post baselines and keep one ongoing monitoring dashboard showing pages crawled per day, average time-to-index, and organic impressions for remediated pages. Use Google Developers for crawl budget guidance and Ranklytics to automate monitoring.
Case Examples, Playbook Templates, and Tracking With Ranklytics
Direct point: A short, prioritized playbook and a tight monitoring sheet beat endless audits. When technical seo crawl budget is the suspect, your goal is to stop waste, restore indexation of priority pages, and prove the outcome with a few reliable metrics.
Sprint-ready playbook (two-week template)
- Day 1 – Rapid triage: Run a Ranklytics Site Health scan, pull Google Search Console Coverage and Crawl Stats, and export a one-week server log sample for Googlebot hits. Focus only on top 200 landing pages by organic sessions.
- Day 2-4 – Contain the worst waste: Apply quick rules on low-effort high-cost items: parameter noindex for faceted URLs, collapse redirect chains on top landing pages, and remove accidental noindex on revenue pages.
- Day 5-9 – Stabilize indexation: Clean the XML sitemap to include only canonical, indexable pages; fix canonical tags on 10 highest-traffic pages; resubmit sitemap and update internal linking to surface priority pages.
- Day 10-14 – Measure and iterate: Track pages crawled per day, time-to-index for changed pages, and organic impressions on remediated URLs. Hand off medium-effort items like parameter handling policy or CMS template fixes to the next sprint.
Practical insight: Quick fixes like sitemap cleanup and collapsing redirect chains often produce measurable gains faster than large architectural changes. But those quick wins are not a substitute for a canonical strategy when the site relies on faceted navigation.
Minimum monitoring sheet to prove impact
| Metric | Baseline | Target | Where to get it | Frequency |
|---|---|---|---|---|
| Pages crawled per day | Export value | 20-50% increase on priority sections | Google Search Console | Daily |
| Time to index (new/updated pages) | Average days | Reduce by 50% for priority pages | Server logs + Ranklytics Indexation report | Weekly |
| Organic impressions for remediated pages | 7-day baseline | Positive trend in 2-6 weeks | Google Search Console + Ranklytics keyword tracker | Weekly |
| Crawl efficiency (indexed URLs / crawl requests) | Current ratio | Improve ratio by reducing low-value URLs | Server logs + Screaming Frog | Weekly |
| Redirect chains on top landing pages | Count | Zero chains on top 50 pages | Site crawl tools + Ranklytics Site Health | One-off then weekly |
Concrete case examples
Ecommerce faceted navigation: A mid-market store generated millions of parameter URLs. The team applied selective parameter noindex, removed parameter pages from the XML sitemap, and tightened internal linking to canonical category pages. Result: Googlebot shifted crawl to canonical product and category pages and the site recovered discovery capacity for new product pages over several weeks.
Documentation portal with pogo sticking: A SaaS docs page ranked but suffered rapid returns to SERP because the page did not answer the primary how-to query immediately. The fix combined a concise lead solution, a table of contents above the fold, and a 30 percent improvement in TTFB. Rankings and time-on-page recovered within a couple of weeks after recrawl.
Trade-off to accept: Using noindex cleans crawl waste fast but removes a URL from organic discovery and any direct search equity it held. When link equity is present, prefer canonicalization and sitemap exclusion paired with internal link redistribution instead of blanket noindex.
How to use Ranklytics at each stage
- Discovery: Run the automated Site Health scan to surface indexation mismatches and crawl alerts, then export the list of affected priority pages.
- Prioritization: Use Ranklytics keyword tracker to map impacted pages to traffic potential and build a simple priority matrix for engineering sprints.
- Execution: Attach remediation tasks to pages inside Ranklytics content planner so the content owner and engineer share the same checklist and evidence.
- Validation: Use the Ranklytics indexation report and keyword rank history to correlate fixes with ranking recovery, and set an alert for indexation divergence.
Next consideration: After initial wins, schedule a follow-up sprint to address canonical policy and parameter handling; short-term fixes will revert if the underlying URL-generation behavior is not corrected.

Written by
ranklytics