


Table of Contents
- 1 How One Content Team Rebuilt Trust After Google Penalized Their AI Content
- 1.1 1. What triggered the review and how the penalty presented
- 1.2 2. How to spot ai-generated text at scale
- 1.3 3. Prioritization matrix for remediation
- 1.4 4. Concrete remediation steps the team executed
- 1.5 5. Restoring trust with users and search engines
- 1.6 6. How Ranklytics fit into the recovery workflow
- 1.7 7. Playbook artifacts and templates to ship to the team
- 1.8 8. Metrics, expected timelines, and realistic outcomes
- 1.9 9. Governance and prevention blueprint
How One Content Team Rebuilt Trust After Google Penalized Their AI Content
When a high-volume content team watched organic traffic collapse after Google flagged a large portion of their output, they had to move fast to diagnose the damage and stop further harm. This case study shows how to spot ai-generated text at scale, triage which pages to prune or rewrite, and rebuild both search visibility and user trust without throwing away productivity gains from AI. You will get a step-by-step playbook: the signals used, a prioritization matrix, editorial checklists, and measurable milestones so your team can recover methodically instead of guessing.
1. What triggered the review and how the penalty presented
Immediate observation: organic visibility collapsed across entire topic clusters before anything resembling a manual notice arrived. The first sign was not a message from Google but a pattern in the analytics and editorial channels – falling impressions in Search Console, multiple pages losing position simultaneously, and editors reporting reader complaints about shallow, repetitive answers.
Timeline and first triage
First three actions: freeze new publishing, export traffic and ranking baselines, and build a content inventory keyed by template and author. Freezing publishing stops adding noise – it costs time but prevents more low-value pages from widening the penalty surface. Use a site audit tool to speed the inventory; Ranklytics was used in this case to export pages with impressions above a minimal threshold and surface clusters that shared identical outlines. See How to Do an SEO Audit: A Beginner-Friendly Guide to Boost Your Traffic – Ranklytics.
- Search signals: broad drops in impressions and average position limited to dozens or hundreds of pages in similar topic areas.
- Editorial flags: complaints from readers, low time on page, and user feedback noting repetitive phrasing or incorrect facts.
- Publishing pattern: sudden spike in volume with identical templates or thin 300-500 word pages published by multiple writers or a central bot-like source.
Practical limitation to note: detectors and metrics tell you there is a problem but rarely point to a single cause. A cluster of low-quality pages can trigger algorithmic downgrades even if some pages are genuinely useful. Treat detection as a map to prioritize work – not as conclusive evidence of automated authorship. For evidence and guidance on what Google considers useful content see Google Search Central.
Concrete example: the team found hundreds of how-to pages using the same three-bullet opening, identical section headers, and no primary sources. Those pages had impressions but very low engagement. The audit isolated the template, and the editorial team paused that template while they triaged whether to prune, consolidate, or rewrite at scale.
| Signal observed | What it typically indicates | Immediate action taken |
|---|---|---|
| Identical intros across pages | Template-led output with low uniqueness | Flag template, pause publishing, sample pages for manual review |
| High impressions but low time on page | Clickbait or thin answers that do not satisfy user intent | Prioritize for rewrite or consolidation |
| Short pages with no external citations | Surface-level content lacking expertise or sources | Add source requirements or mark for noindex if low value |
Next consideration: move from incident triage to the forensic step – how to spot ai-generated text at scale and decide which pages to prune, rewrite, or keep.
2. How to spot ai-generated text at scale
Straight to the point: detecting AI output at scale is a two-layer problem – statistical triage followed by editorial verification. Automated tools give you signals, not verdicts; human review decides action.
Automated signals to run across your corpus
What to run at scale: batch AI-likelihood scores, n-gram repetitiveness checks, and simple textual diversity metrics. Use Originality.ai or comparable APIs for sitewide scoring, then surface pages with unusually low lexical variety or identical phrasing patterns.
- Token distribution anomalies: run GLTR on a stratified sample to check for unnaturally high probability tokens (GLTR).
- N-gram repetition: flag pages with the same 5-10 word sequences across many URLs – a sign of templated or copy-pasted AI output.
- Sentence length variance: low variance often means mechanical prose; calculate standard deviation per page and rank against site baseline.
- Similarity clustering: cluster content by cosine similarity to find large groups of near-identical pages that lack unique angles.
Manual indicators editors must validate
Editorial checks that matter: look for generic openings, missing primary sources, surface-level lists without tradeoffs, and absence of verifiable author expertise. These are the traits automated tools miss or mislabel.
- Repetitive intros and CTAs: identical lead sentences or identical calls to action across pages.
- No original data or quotes: no primary sources, no unique examples, and no subject-matter voice.
- Shallow answers: content skims a topic without acknowledging common objections or tradeoffs.
- Fact gaps or subtle inaccuracies: small factual errors that suggest a lack of real-world checking.
Practical tradeoff: automated detection scales but generates false positives on short pages and heavily edited drafts. Relying only on a probability score wastes editor hours; relying only on humans does not scale. The right tradeoff is sampling flagged buckets rather than reviewing everything.
- Batch score: run an AI-likelihood API and tag pages with high scores.
- Stratified sampling: pick a statistically valid sample from each score bucket for GLTR analysis and human review.
- Editorial triage: apply a simple keep, rewrite, prune rubric after human checks.
- Prioritize by impact: sort flagged pages by impressions, conversion value, or keyword potential before action.
Concrete Example: export pages with low engagement, run an Originality.ai batch to score them, then GLTR-sample 5 to 10 percent of each score bucket for token-probability anomalies. Editors then inspect sampled pages for missing sources and shallow insights and tag each page keep, rewrite, or prune in your CMS.
Key judgment: treat detector outputs as triage tools, not proof. Use relative thresholds – compare a page to your site baseline – and build human sign-off into every remediation path. If you skip that, you will either over-prune legitimate content or leave machine-like pages live.
Next consideration: implement this as a recurring job – automated scoring every week, sampling-driven human review, and a feedback loop so editors can flag false positives. That loop is the difference between catching machine-generated noise and breaking working content.
3. Prioritization matrix for remediation
Start with impact, not suspicion. The quickest wins are pages that attract impressions or conversions but show clear signs of low usefulness or high likelihood of being machine-generated. Use a simple matrix that combines business impact with remediation effort to triage the backlog.
Matrix overview
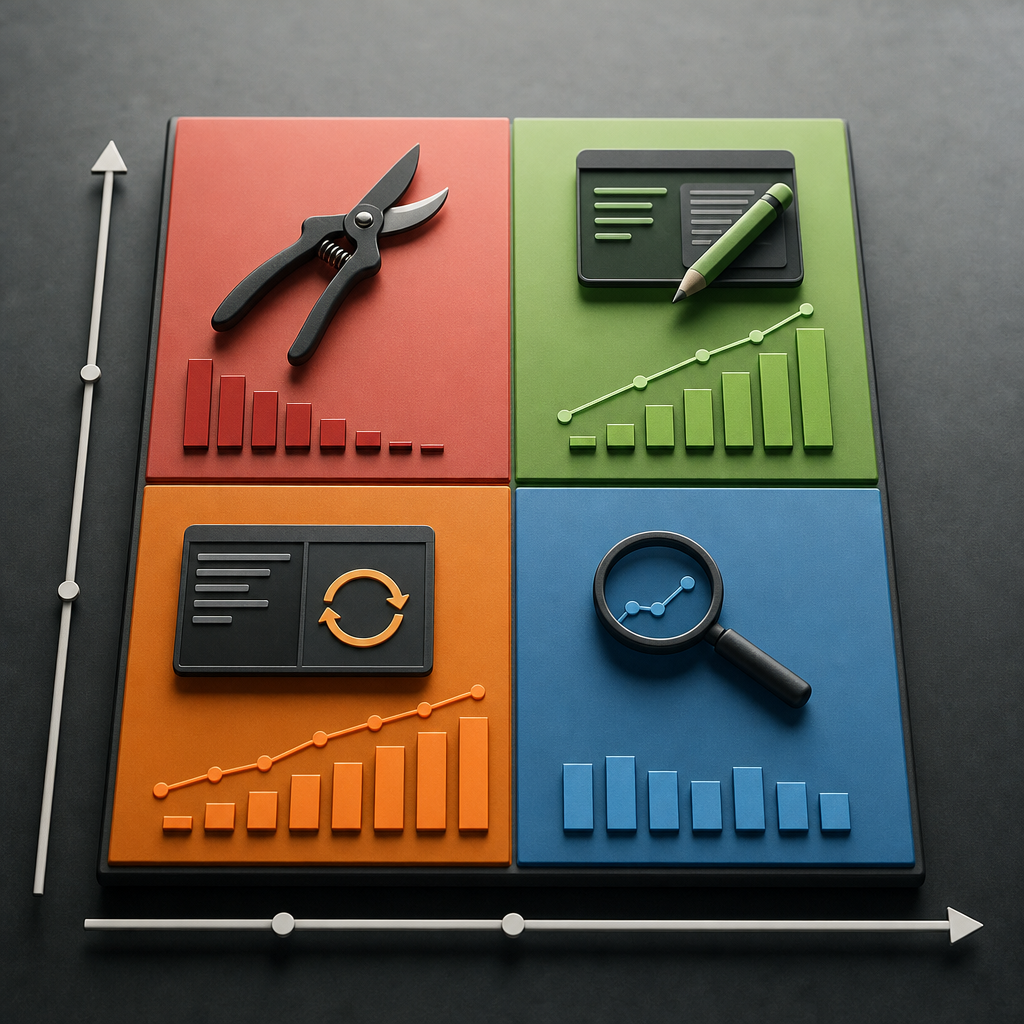
Two axes to use. Put Impact on the vertical axis (impressions, clicks, conversions) and Effort on the horizontal axis (rewrite hours, SME time, design assets needed). Map every flagged page into one of four buckets: Prune, Quick Rewrite, Deep Rewrite, Monitor/Keep and Improve.
| Bucket | When to use it | Typical action | Expected time to effect |
|---|---|---|---|
| Prune | Low impact, high AI-likelihood, duplicate or thin content | Noindex/301 consolidate or delete; merge into stronger pages | Immediate stabilization (days to weeks) |
| Quick Rewrite | High impact, low effort (small factual fixes, citations) | Apply editorial changes, add sources, republish with author info | 4–12 weeks for ranking movement |
| Deep Rewrite | High impact, high effort (expert input, original data needed) | Commission subject-matter rewrite, add interviews/visuals | 12+ weeks; requires promotional amplification |
| Monitor/Keep and Improve | Moderate impact, low AI-signals; already useful but improvable | Incremental edits, internal linking, A/B test headings | Weeks to months; watch engagement metrics |
Concrete decision rules and thresholds
- High priority rewrite: pages with >1,000 impressions last 90 days, CTR <2.5%, average time on page <45s, and AI-likelihood score >0.6 from tools like Originality.ai.
- Prune candidate: pages with <100 impressions, thin content length, high content similarity across site, and repeated template phrasing that matches other pages.
- Deep rewrite candidate: pages that drive conversions or rank in top 10 for valuable keywords but fail quality checks or require SME validation.
- Keep and monitor: pages with decent engagement and low AI-detection signals; schedule periodic checks rather than immediate action.
Practical workflow using Ranklytics. Run a site audit to export pages by impressions and engagement, filter by AI-likelihood score, then tag pages into buckets and assign sprints. Use the content scoring feature to batch pages tagged Quick Rewrite and create rewrite briefs from templates linked to each page. See a sample workflow in the Ranklytics content audit tool: How to Do an SEO Audit: A Beginner-Friendly Guide to Boost Your Traffic – Ranklytics.
Real-world example
Concrete Example: A SaaS publisher had 250 pages flagged after a penalty. The team ran automated AI checks and filtered pages with >500 impressions and AI-likelihood >0.7. Twenty pages landed in High Priority: they rewrote ten with expert quotes and added two original charts, merged five into pillar pages, and pruned five. Within 8 weeks the rewritten pages regained position and time on page improved.
Trade-off to accept. Pruning recovers crawl budget and removes noise fast, but it reduces long-tail coverage and may eliminate marginal referral traffic. Rewriting keeps content breadth but costs editorial time and may not deliver rankings unless paired with promotion or links.
Focus first on pages that move metrics you care about. High-impact, low-effort wins fund the heavier work.
Operational considerations
- Batch by remediation type. Group Quick Rewrites into sprints so editors reuse research and templates.
- Set a crawl and republish cadence. Stagger submissions to Search Console; too many resubmits looks like noise.
- Track ROI per bucket. Measure ranking and engagement deltas per action to refine thresholds — what you prioritize this month should be data-driven next month.
Next consideration: After you tag and act on high-priority pages, build the same matrix into your editorial cadence so new content is scored against impact and effort before publishing — that prevents repeat problems and keeps remediation work focused where it moves the needle.
4. Concrete remediation steps the team executed
Straight action beat theory. The team stopped guessing and ran a repeatable sequence: remove the worst pages, consolidate related thin content, rewrite mid-value assets to a strict editorial brief, verify with humans and detectors, then republish in controlled batches while monitoring signals. Each step had a clear owner, exit criteria, and measurement.
Phase 1 — prune and consolidate (fast wins)
Prune aggressively for recovery speed. Pages with near-zero engagement, duplicated outlines across topics, or zero backlinks were noindexed or removed rather than rewritten when the expected SEO gain was minimal. This reduced noise and freed crawl budget.
- Action: Bulk noindex low-value pages in weekly batches and track indexed page count.
- Consideration: Pruning removes long-tail opportunities – only prune after checking impressions and potential with a tool like Ranklytics or a site audit (How to Do an SEO Audit).
- Trade-off: Faster signal recovery versus permanent content loss; export lists first so you can restore useful URLs later.
Phase 2 — disciplined rewrites using a strict brief
Change the input to change the output. Rewrites were not cosmetic. Editors received briefs with mandatory deliverables: original reporting or data, two expert quotes, explicit source list, unique visual, and a measured success criteria tied to engagement and ranking.
- Brief fields: target keyword, why the page failed (engagement/duplicates), required primary sources, word count range, and internal link targets.
- Quality gates: subject-matter reviewer sign-off, fact-check pass, and a readability score threshold.
- Practical constraint: Rewriting at scale is costly; prioritize pages with search potential rather than rewriting everything.
Concrete Example: The team merged 120 thin how-to and FAQ pages about onboarding into a single 4,200-word pillar that included a proprietary checklist, two interviews with product leads, and three screenshots. That single consolidation required fewer pages to be crawled, improved internal linking, and produced measurable lifts in time on page within six weeks.
Phase 3 — human verification and staged republish
Verification beats wishful thinking. Before republishing, every page went through a human checklist and a detector pass. Use automated tools to flag residual statistical anomalies, but rely on human reviewers to confirm factual accuracy, unique insight, and voice consistency.
- Step 1: Run an AI likelihood check (GLTR or Originality.ai) to see if the rewrite removed machine-like patterns.
- Step 2: Editorial QA that verifies sources, quotes, and hands-off tests for readability and nuance.
- Step 3: Staged republish: send batches of 50–200 pages for recrawl rather than all at once to avoid crawl noise and to observe early signals.
Limitation: Automated detectors will give false positives and negatives. They are useful to confirm improvements, not to be the final arbiter of publishing decisions—human judgment must prevail.
Phase 4 — monitoring, iteration, and governance
- Metrics to watch: impressions, average position, time on page, bounce/pogo-stick rate, and conversions for rewritten pages.
- Iteration cadence: review weekly for the first two months after republish, then biweekly; log editorial changes alongside metric deltas.
- Governance: introduce a mandatory human-in-the-loop policy for any AI-assisted draft and schedule quarterly spot checks to how to spot ai-generated text regressions.
Final consideration: Rewriting everything is seductive but expensive and slow. The smarter path is surgical pruning, high-quality rewrites where value exists, and human verification backed by detection tools and monitored republish cadence. That sequence fixed the immediate penalty and created rules that prevented the same failure mode from recurring.
5. Restoring trust with users and search engines
Immediate trust signals to add: Start with things visitors and search reviewers can verify in seconds. Add verifiable author pages, clear publication and revision notes, visible primary sources, and an editorial note that explains the review steps you took and the tools used to detect AI content. For public documentation of policy changes include a short log that states the human in the loop process and links to evidence such as expert interviews or original data.
What to add to pages now
- Author verification: Add an author page with a short bio, verifiable credentials, and a link to a professional profile. This is not a cosmetic byline change – it is a signal of accountability.
- Editorial note: Publish a brief note on the page describing the quality checks performed and the tools used, for example GLTR or Originality.ai, so reviewers can see how you addressed concerns about how to spot ai-generated text.
- Primary sources and original assets: Embed at least one primary source, a screenshot, data table, or original quote that cannot be found verbatim on hundreds of other pages.
- Transparent revision history: Show when the page was reviewed, what was changed at a high level, and who signed off. That reduces suspicion from both users and algorithmic reviewers.
- Contextual signals: Add internal links to pillar content and related expert pages, and avoid generic tag or category pages that create low value clusters.
Concrete Example: The team converted boilerplate bylines into verified author pages that include a two sentence expertise summary and a LinkedIn link, then added a three line editorial note explaining that the article was fact checked and checked with statistical detectors like GLTR. They also replaced a stock list with one original interview excerpt and an internal analysis table. After these changes the pages showed clearer visitor engagement patterns and fewer immediate bounces in the pages that were republished.
Tradeoff and limitation: Adding visible credibility elements is necessary but not sufficient. Author pages and editor notes will not fix thin content or weak topical depth – they only reduce credibility risk. If the underlying page lacks unique insight, invest that effort where organic impact justifies the cost instead of plastering on trust signals for low value pages.
Outreach and earned signals: For higher value pages run a short outreach playbook: secure one or two expert quotes, pitch the piece to three relevant newsletters or journalists, and request citations from partners. Backlinks and referrals take time but they are the clearest external signal that your content is useful and not mass produced.
- What to monitor as evidence of regained trust: time on page, lower pogo stick behavior, conversion rate for the page, impressions and average position for target queries, and the pattern of queries leading to the page.
- What signals mean you still have work to do: short sessions combined with high impressions, repeated user exits to search results, and pages with many similar sibling pages that add no new value.
Practical judgement: Be honest with stakeholders about timing. Quick visible fixes buy time and reduce pressure, but durable recovery requires republishing with original research or expert input on a prioritized set of pages. Use your analytics to pick those pages – then treat visible credibility signals as amplification, not a replacement, for real content improvement. For implementation guidance see How to Show Up in Google AI Overviews (Source Selection, Explained) and review Google guidance on helpful content at Google helpful content update.
Next consideration: Prepare a public changelog and a handful of signature pieces with original reporting. Those are the durable signals that restore trust over months, not days.
6. How Ranklytics fit into the recovery workflow
Direct role: Ranklytics became the operational hub for the audit, triage, and ongoing quality controls rather than a black box predictor. The platform did three things the team needed: surface pages that matched the signals associated with low value or synthetic content, provide a ranked list to prioritize work, and enforce operational controls so fixes stuck.
How Ranklytics translated detection signals into work
Ranklytics does not replace dedicated AI detectors but it organizes the messy signals you already have into actionable buckets. It pulls engagement metrics, similarity scores, and AI likelihood outputs into a single content score so editors can see why a page is flagged for review when investigating how to spot ai-generated text.
- Surface: run a sitewide audit to list pages by content score and impressions – this finds problematic clusters fast. See How to Do an SEO Audit.
- Prioritize: filter pages with high impressions and low engagement, then sort by content score to pick rewrite candidates or prune targets.
- Operationalize: export batches, attach remediation tags, and assign sprints so fixes are repeatable and recorded for downstream monitoring.
Practical insight: do not treat the content score as gospel. Automated scores are correlation tools – they surface likely problems but they also flag nuanced expert pieces and longform updates that need human judgment. Always calibrate thresholds with a random human sample before mass action.
Concrete example of daily use
Concrete Example: the team exported pages with impressions above 500 and average time on page below the site median, then annotated them into three buckets – prune, rewrite, monitor. Editors used Ranklytics content briefs for rewrite sprints and tracked keyword rank changes in the same workspace so the impact could be measured without manual spreadsheets. This kept the remediation loop tight and auditable.
Limitation and tradeoff: enabling automated alerts for publication velocity prevented a recurrence but slowed output. The editorial team had to accept a temporary cut in throughput while quality gates were installed. That tradeoff reduced risk of repeat penalties and forced the team to focus on higher value pieces.
- Unique control: role based publishing flags so only content that passed human verification could go live.
- Calibration step: sample 200 flagged pages and run a secondary check with GLTR or Originality.ai – use findings to tune Ranklytics thresholds.
- Audit trail: timestamped remediation notes preserved the decision rationale teams can show if reviewing outcomes with stakeholders or auditors.
Ranklytics adds value by turning detection signals into a repeatable workflow, not by promising perfect AI detection.
If you want the audit to feed your governance, add scheduled monthly quality checks, automated alerts when publication velocity spikes, and a fixed quota for human-reviewed AI assisted drafts. For reference on the signals Google uses for helpful content, see Google Search Central.
7. Playbook artifacts and templates to ship to the team
Start with the small set of artifacts that actually change behavior. Shipping documents is easy; getting editors to use them is hard. Focus on templates and checklists that remove judgment calls during triage and rewrites so reviewers spend time improving content, not arguing about process.
Essential artifacts to include in the playbook
- Editor quality checklist: A copy-paste checklist for CMS draft review covering source verification, unique contribution, E E A T fields, visual asset checklist, and final QA steps. Keep it under eight items so it gets used.
- Rewrite brief template: Required fields only: target keyword, why the existing page failed, mandatory primary sources, exact examples to include, success metrics, and a maximum time budget for the rewrite.
- Content scoring rubric / editor scorecard: A three-tier scoring matrix that converts qualitative checks into a pass/fail or numeric score tied to publish/noindex decisions.
- Expert outreach email template: Short intro, one clear ask, list of questions, and permission language to publish full name/credentials. Include an alternate ask for a 15-minute call.
- Triage board CSV / tag taxonomy: Standard tags (prune, rewrite, merge, monitor) and priority flags so the CMS and task manager agree on next steps.
- Rollout checklist for republish requests: Steps for incremental republishing and Search Console inspection without spamming crawlers.
How to use each template in practice
- Triage: Export Ranklytics or Search Console data, filter by impressions with low engagement, then apply the triage board tags. Use the editor quality checklist inside the CMS as the first gate.
- Assign rewrite briefs: For any page tagged rewrite, the brief owner fills the Rewrite brief template and assigns an editor plus a subject-matter reviewer. Require a minimum of one primary source and one unique data point.
- Expert outreach: Send the expert outreach email from the template within 48 hours of assignment. Attach the brief so contributors see context and exact placement of quotes.
- Close the loop: Use the content scoring rubric post-edit. Pages that fail get noindexed or escalated for a second rewrite.
Practical insight – tradeoff: More fields in a template increase signal quality but reduce throughput. We found requiring one primary source and one unique insight hits the balance: it excludes purely synthetic text while keeping volume manageable. If you require two expert quotes on every page you will fall behind.
Concrete Example: An editor opens a page flagged by Ranklytics for low engagement. They paste the URL into the Rewrite brief template, note that the page lacks primary sourcing, list two sources to consult, and set success criteria (10% lift in time on page). The outreach template is used to request a 10-minute expert quote; the returned quote is pasted into the brief and the page is republished under the original author with an updated author bio.
If you need to teach how to spot ai-generated text, include one short guided example in the editor checklist showing three AI writing indicators versus an acceptable human rewrite.
Final takeaway: Make templates do the work of policy. Clear, minimal artifacts that enforce source checks, measurable success criteria, and a fast expert outreach loop will change output quality faster than hiring or heavier tool integrations. For a practical audit to pair with these templates, see How to Do an SEO Audit: A Beginner-Friendly Guide to Boost Your Traffic.
8. Metrics, expected timelines, and realistic outcomes
Key point: focus metrics on human value and recovery signals, not on detector scores alone. AI likelihood tools are useful for triage, but the metrics that actually show recovery are engagement, indexing, and ranking behaviour.
What to monitor weekly and monthly
- Organic sessions (weekly): track short windows for stabilization after pruning or republishing; a flat or slowly rising trend is good, sudden volatile swings are a red flag.
- Impressions and average position (weekly/monthly): impressions tell you exposure, position shows whether rewrites move the needle for target queries.
- Pages indexed (weekly): pruning should reduce low-value indexed pages; unexpected index drops across important sections indicate crawl or site-level problems.
- Time on page and pogo-sticking signals (monthly): meaningful increases imply content is meeting user intent; small changes in time on page are noisy — watch sustained shifts.
- CTR for target snippets (weekly): better titles/meta and richer content should raise CTR even before rankings improve.
- Conversion or micro-conversion rate (monthly): the business metric that justifies rewrite cost; use a simple upstream goal like newsletter signups if revenue is rare.
Practical insight: treat AI-detection outputs as a prompt to audit, not a verdict. Teams obsessed with how to spot ai-generated text scores will waste time fixing pages that are actually thin, duplicated, or poorly sourced. Prioritise signals that affect users and Google's helpful content algorithm.
Realistic timeline and milestones
Typical cadence: expect visible stabilization within 2–6 weeks after aggressive pruning or taking worst pages out of index; first meaningful ranking gains for rewritten pages commonly appear in 4–12 weeks; full recovery across a large site can take several months depending on crawl budget, backlink profile, and volume of changes.
Trade-off to plan for: pruning yields faster stabilization but reduces surface area for long-tail traffic; rewriting is slower and costlier but preserves potential. If you lack editorial capacity, prune aggressively and republish pillar content gradually.
Concrete Example: a mid-sized publisher removed a batch of thin topical pages and consolidated them into three pillar articles, then rewrote 120 mid‑traffic pages with primary sources. They saw session volatility settle in three weeks and steady ranking gains for the pillars after eight weeks. The point: consolidation plus prioritized rewrites beat trying to fix thousands of low-value pages at once.
Experimentation and documenting what works
How to run useful experiments: pick a sample set (50–200 pages) with comparable traffic and intent, keep an unedited control group, log every editorial change in a single spreadsheet, and monitor those pages in Search Console and your analytics for 12 weeks. Avoid changing other variables on those URLs while the test runs.
What teams misunderstand: SEO A/B testing is not just about swapping headlines. The most predictive signals are structural: added unique sources, author attribution, and original data points. Tests that only rephrase content rarely move the needle.
- Signals that show progress: rising average position for target keywords, higher time on page, reduced bounce on target landing pages, and growing impressions for semantically related queries.
- When to accelerate: if a rewrite template produces >10% lift in average position across the test set within 8–12 weeks, scale that template.
- When to stop: if no meaningful movement after 12 weeks, revert to the control and re-evaluate the brief.
Next consideration: set explicit checkpoints at 3, 8, and 12 weeks with ownership assigned — if metrics are not trending as expected at any checkpoint, switch strategy (more pruning, different templates, or investment in links) rather than doubling down by default.
9. Governance and prevention blueprint
Governance stops mistakes from repeating; it does not chase perfection. Set rules that make good editorial decisions the default and measurable, then enforce them. Treat governance as product management for content: define acceptable inputs, required outputs, and error-handling paths.
Core policy elements to adopt now
- Human review gate: Every AI-assisted draft must pass a named editor review before scheduling. The gate is binary: approve or reject — no conditional publishes.
- Provenance metadata: Require a short machine-readable field in the CMS that records whether the draft used AI, which model/tool, prompt summary, and the editor who approved it.
- Minimum originality threshold: Set a content score floor (use a mix of automated AI-likelihood tools and internal quality metrics) that must be met before publishing.
- Mandatory sourcing: Each factual claim above a threshold (e.g., statistics, medical advice, legal statements) must include an inline source or an editor sign-off confirming verification.
- Author accountability: Published pieces must list a responsible author or editor with a link to an author page describing expertise and contact method.
- Sampling and audits: Define a statistical sampling plan (see example below) for monthly spot checks using both automated detectors and human review.
- Publication cadence control: Limit daily AI-assisted publish volume per editor and set automated alerts when velocity spikes.
Trade-off to accept: tighter governance slows output and raises costs. You will produce fewer pieces, but each one is less likely to be low-value or trigger search penalties. That trade-off wins when your organic traffic and brand trust matter more than raw volume.
Operational controls and enforcement
- Automated guardrails: Integrate AI-likelihood checks (GLTR, Originality.ai) as pre-publish alerts, not hard blocks. Flagged rates above a threshold should open an editorial workflow ticket.
- Escalation ladder: If X% of a single editor's outputs fail checks in a week, suspend AI publishing privileges for that editor pending retraining and supervised sprints.
- Revision and rollback policy: Keep immutable version history and a clear rollback pathway (noindex + archive) for content found later to be low quality or misleading.
- Contract clauses: For freelancers, require disclosure of AI use, deliverables that include primary reporting or unique assets, and a clause allowing rework if content fails quality audits.
Limitation: automated detectors are noisy. Use them as early warning systems, not final arbiters. Human review must focus on usefulness and original contribution, not only whether a sentence looks machine-generated.
Concrete example — a sampling plan that scales
Concrete Example: The team implemented a monthly sample of 5% of published pages plus 100 highest-impression pages. Automated tools flagged suspicious pages; flagged pages were routed to a senior editor for a 10-minute audit. If more than 20% of audited pages failed, the team paused AI-assisted publishing and ran a targeted retraining sprint for authors and editors. This approach caught pattern errors early without auditing every page.
Real-world application: enforce the sample with a dashboard and calendar reminders. Use Ranklytics to export candidate pages by impressions and engagement, then feed those into your detector and audit queue.
What teams commonly misunderstand: many think governance equals audit after the fact. That is backwards. Preventative controls – provenance fields, hard editor gates, and publishing quotas – reduce remediation cost far more than post-publish audits. Audits find problems; governance prevents them from proliferating.
Next consideration: link governance to incentives. Tie part of editorial performance reviews to quality metrics (time on page, return visits) rather than raw output volume. That alignment stops gaming the system and preserves pace with quality.

Written by
ranklytics